
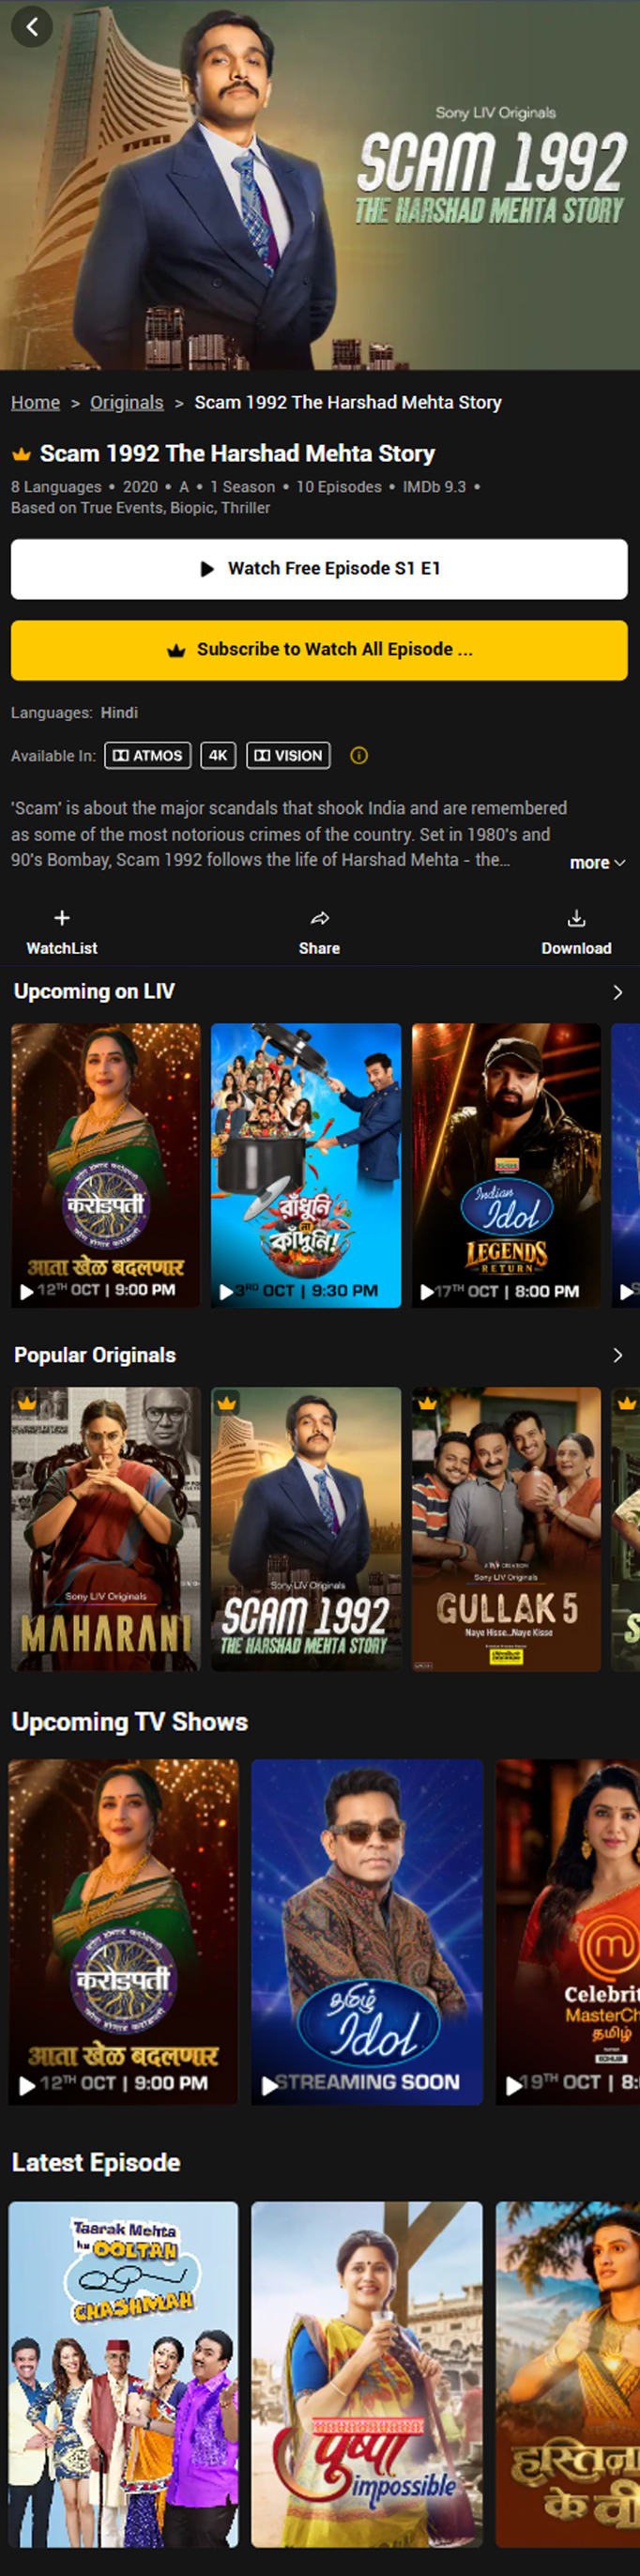
Our Sony LIV Scraper enables businesses to collect structured information from Sony LIV, including movies, TV shows, episodes, genres, languages, ratings, descriptions, sports programming, and streaming metadata. Designed for scalable OTT research, the solution organizes large volumes of content information into consistent datasets that can support catalog analysis, competitive research, content performance evaluation, and programming intelligence. With a reliable Sony LIV Scraping Service, businesses can automate recurring data collection and receive updated information according to their research requirements.

Collect diverse streaming titles, episodes, genres, languages, ratings, and descriptions using Sony LIV OTT Scraper to support organized research and detailed content analysis.

Gather structured title information, release dates, cast details, duration, descriptions, genres, and languages to create comprehensive datasets for OTT research and comparison.

Organize extensive datasets through Sony LIV Catalog Data Extraction to evaluate catalog composition, category distribution, programming patterns, content availability, and changes.

Capture sports events, leagues, schedules, categories, teams, and related programming details to support sports-focused streaming research, audience analysis, and content planning.

Perform Sony LIV Movie Metadata Extraction to collect title attributes, release information, genres, cast details, duration, descriptions, and language information systematically.

Track new releases, catalog changes, episode additions, removals, and metadata updates to maintain relevant datasets for continuous OTT research, analysis, and monitoring.
import requests
from bs4 import BeautifulSoup
from urllib.parse import urljoin

HEADERS = {
"User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64)",
"Accept-Language": "en-US,en;q=0.9",
}

def get_text(soup, selector):
element = soup.select_one(selector)
return element.get_text(" ", strip=True) if element else "N/A"

def scrape_sonyliv_content(page_url):
try:
response = requests.get(
page_url,
headers=HEADERS,
timeout=15
)
response.raise_for_status()
except requests.RequestException:
return None

soup = BeautifulSoup(response.text, "html.parser")

content = {
"Title": get_text(soup, "h1"),
"Genre": get_text(soup, ".genre"),
"Language": get_text(soup, ".language"),
"Rating": get_text(soup, ".rating"),
"Release_Date": get_text(soup, ".release-date"),
"Description": get_text(soup, ".description"),
"Content_URL": page_url
}
return content

# Example publicly accessible Sony LIV content URL
sonyliv_url = "https://www.sonyliv.com/example-content"
result = scrape_sonyliv_content(sonyliv_url)

if result:
for field, value in result.items():
print(f"{field}: {value}")
else:
print("Content data could not be retrieved.")
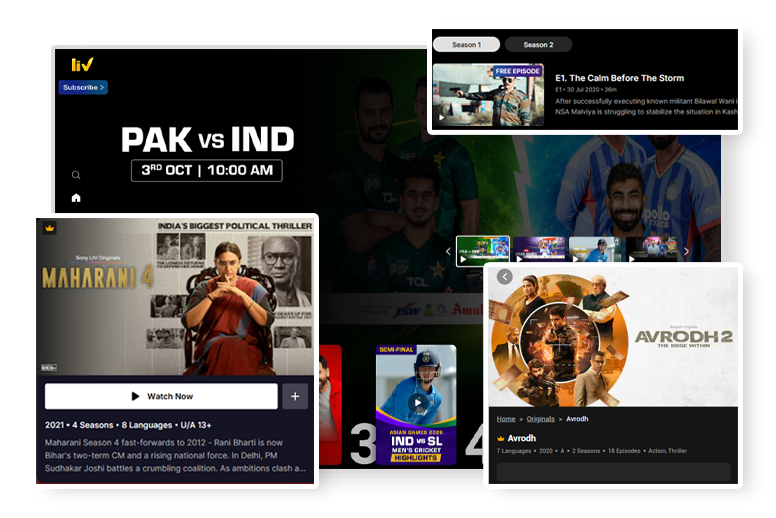
Analyze streaming libraries with Sony LIV Movie and TV Show Data to compare genres, languages, ratings, releases, episodes, and programming patterns across entertainment categories.
Evaluate title performance through Sony LIV Content Data Extraction by examining episodes, ratings, descriptions, categories, release information, and content trends systematically.
Study sports programming through Sony LIV Sports Content Data to assess events, leagues, schedules, categories, tournaments, and programming patterns for specialized streaming research.
Support competitive research through Sony LIV OTT Data Extraction Service by collecting structured programming information, catalog attributes, metadata, and category details.
Collect and categorize titles, episodes, genres, languages, ratings, and release information through Sony LIV Movie and TV Show Data for systematic OTT research.
Clean & standardize entertainment data using Sony LIV Content Data Extraction, creating consistent datasets for content analysis, comparison, and recurring research requirements.
Organize categories, titles, episodes, availability, and programming details through Sony LIV Catalog Data Extraction to support comprehensive streaming catalog analysis and comparisons.
Structure release dates, genres, cast details, descriptions, durations, and ratings with Sony LIV Movie Metadata Extraction for detailed OTT content evaluation and research.
Use Sony LIV Scraper responsibly by collecting only publicly accessible information, respecting applicable laws, website terms, intellectual property rights, privacy requirements, and reasonable request limits.
Contact UsEffortlessly managing intricacies with customized strategies.
Mitigating risks, navigating regulations, and cultivating trust.
Leveraging expertise from our internationally acclaimed team of developers
Reliable guidance and assistance for your business's advancement
