Collect structured anime titles, episodes, genres, ratings, metadata, release details, and streaming information with our HiAnime Scraper, designed for businesses, researchers, analysts, and entertainment data projects. Through HiAnime Data Scraping, the solution helps monitor changing catalogs, compare content attributes, analyze episode availability, and organize valuable streaming insights. It can also support HiAnime Subscription Price Data Scraping for tracking subscription-related pricing information and evaluating changes across the entertainment landscape.

Gather extensive anime titles, genres, ratings, descriptions, release details, and streaming attributes while HiAnime OTT Data Scraper supports organized catalog research and analysis.

Map anime catalogs across genres, languages, release statuses, and availability details, helping teams structure entertainment information for comparison, reporting, and content intelligence.

Collect episode numbers, titles, availability, and series information through HiAnime Episode Scraper, supporting accurate datasets for ongoing content analysis and monitoring requirements.

Extract descriptions, genres, ratings, release dates, content status, and classifications, creating consistent metadata records that simplify catalog evaluation, comparison, and research activities.

Connect HiAnime Scraper API with dashboards, databases, analytics platforms, and internal applications to streamline structured data delivery and simplify recurring entertainment workflows.

Track newly added titles, catalog changes, episode updates, ratings, and streaming attributes through scalable extraction workflows designed for continuous entertainment data monitoring.
import requests
from bs4 import BeautifulSoup

REQUEST_HEADERS = {
    "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64)",
    "Accept-Language": "en-US,en;q=0.8",
}

def extract_hianime_details(page_url):
    try:
        response = requests.get(
            page_url,
            headers=REQUEST_HEADERS,
            timeout=15
        )
        response.raise_for_status()
    except requests.RequestException:
        return None

    soup = BeautifulSoup(response.text, "html.parser")

    title_node = soup.select_one("h1")
    description_node = soup.select_one(".description, .film-description")
    rating_node = soup.select_one(".rating, .film-rating")
    genre_nodes = soup.select(".genres a, .film-genres a")
    episode_node = soup.select_one(".episode-number, .ep-item")

    return {
        "Title": title_node.get_text(strip=True) if title_node else "N/A",
        "Description": description_node.get_text(" ", strip=True)
        if description_node else "N/A",
        "Rating": rating_node.get_text(" ", strip=True)
        if rating_node else "N/A",
        "Genres": [
            genre.get_text(strip=True)
            for genre in genre_nodes
        ] or ["N/A"],
        "Episode_Info": episode_node.get_text(" ", strip=True)
        if episode_node else "N/A"
    }

# Example HiAnime page URL
hianime_url = "https://example.com/anime/sample-title"

anime_data = extract_hianime_details(hianime_url)

if anime_data:
    print(anime_data)
else:
    print("Unable to retrieve anime data.")
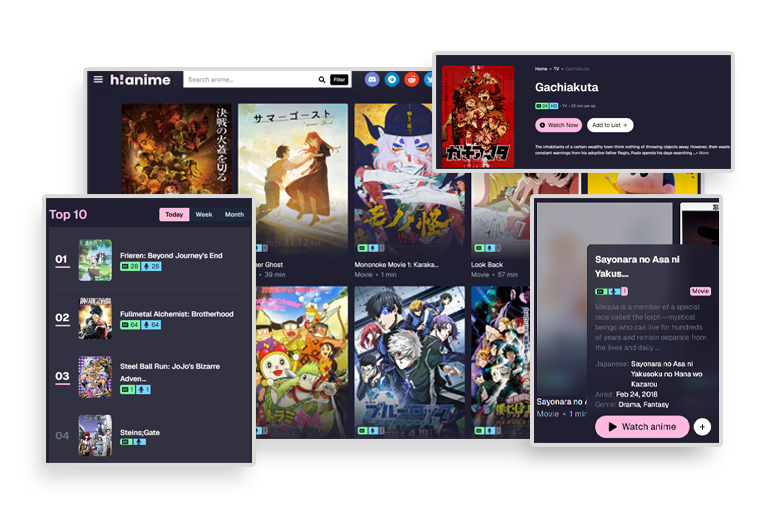
Compare anime titles, genres, ratings, release information, and availability using HiAnime Web Scraper to evaluate catalog positioning, content variety, and competitive OTT trends.
Analyze titles, metadata, episodes, genres, and streaming attributes through OTT Platform Data Scraper to support content planning, catalog comparisons, and entertainment market research.
Examine ratings, popular titles, genres, episode availability, and catalog patterns when you Scrape HiAnime Data for audience preferences, engagement trends, and content decisions.
Build structured anime datasets with Anime Data Scraping API for recommendation engines, research, analytics applications, content intelligence projects, and scalable entertainment data workflows.
Identify relevant anime pages, titles, genres, ratings, metadata, and availability fields through HiAnime Data Scraping, creating organized records for comprehensive OTT content analysis.
Transform collected entertainment information into consistent OTT Datasets, making records easier to analyze, compare, store, manage, and integrate across research workflows.
Transfer processed anime records into databases, dashboards, analytics platforms, and internal applications through HiAnime Scraper API for efficient, automated, and recurring data distribution.
Collect episode numbers, titles, availability, and series-level details using HiAnime Episode Scraper, maintaining accurate content records for ongoing OTT monitoring, analysis, and research.
Use HiAnime Scraper responsibly by collecting publicly accessible information, respecting applicable laws, website terms, copyright requirements, robots directives, and reasonable request limits.
Contact UsEffortlessly managing intricacies with customized strategies.
Mitigating risks, navigating regulations, and cultivating trust.
Leveraging expertise from our internationally acclaimed team of developers
Reliable guidance and assistance for your business's advancement
