.gif)


What Makes Headless Browser Scraping for Enterprise Scale Stable Across Complex Website Workloads?
Introduction
Modern digital ecosystems rely heavily on continuous data extraction to power operational decision-making. As websites become increasingly sophisticated with client-side rendering and interactive JavaScript frameworks, traditional request-based crawlers often fail to parse dynamic content reliably. To overcome these limitations, modern organizations implement Headless Browser Scraping for Enterprise Scale to bypass complex firewall architectures and safeguard large automated pipelines.
Deploying headless browsers at scale requires balancing memory overhead with speed. Large organizations leverage automated headless instances to render complete Document Object Models (DOMs), execute custom scripts, and simulate real user interactions effortlessly. Implementing Enterprise-Scale Web Crawling Solutions ensures that high-volume extraction workflows remain consistent even when targeting heavily protected target websites.
Architecting a resilient extraction pipeline involves robust proxy management, session handling, and dynamic resource allocation. By shifting from simple HTTP requests to browser-level automation, engineering teams eliminate data gaps caused by client-side security checks. This strategic shift transforms unstructured dynamic web environments into clean, reliable data streams for core business analytics.
Technical Infrastructure Systems For Scalable Dynamic Browser Rendering
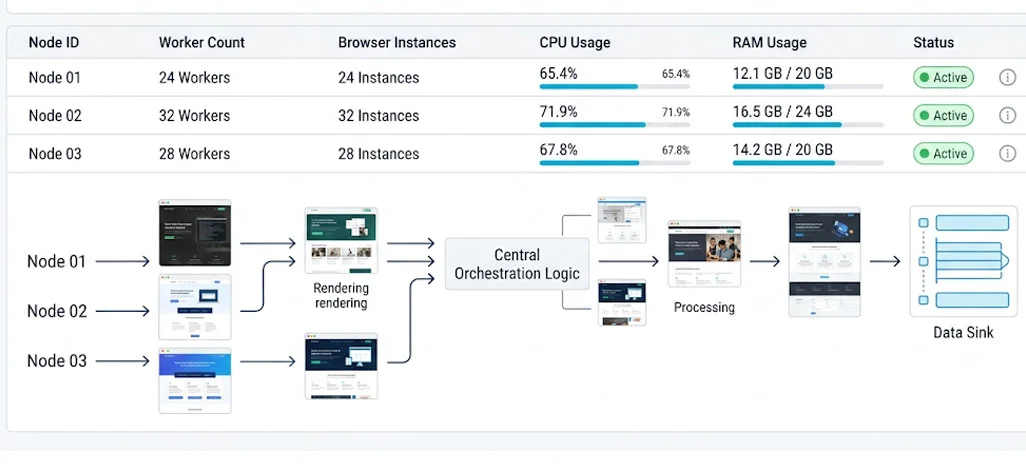
Building a high-throughput extraction environment requires server orchestration capable of handling heavy concurrent background browser processes without overloading host resources. Engineering teams must isolate headless browser instances in containerized nodes to manage CPU allocation, prevent memory leaks, and optimize network requests during intensive data harvesting operations across complex sites.
Deploying a flexible Scalable Web Scraping API allows modern data engineering teams to outsource low-level instance management, network request routing, and DOM rendering overhead. This centralized integration layer simplifies infrastructure scaling while keeping throughput performance high and consistent across massive cross-domain workloads.
To maintain maximum efficiency during daily data extraction tasks, technical teams rely on standardized infrastructure management rules:
- Distributed containerized node clusters for load distribution.
- Automated memory recycling routines for worker instances.
- Optimized headless engine flags to reduce network footprint.
| System Metric | Base Request Pipeline | Automated Browser Architecture |
|---|---|---|
| DOM Execution Capability | Static Content Only | Full Dynamic Script Execution |
| Average Extraction Accuracy | Standard Baseline | Significantly Higher Completeness |
| Resource Overhead Profile | Minimal CPU Usage | Containerized Resource Allocation |
| Target Security Resilience | Basic Protection Handling | Advanced Interaction Handling |
Operating modern extraction pipelines demands effective execution of modern Browser Automation for Scraping to extract content accurately from client-side dynamic applications. By loading the full DOM tree before capturing structured data elements, automated nodes ensure complete resource execution and prevent missing records across single-page applications.
Advanced Protection Bypass Methods For Enterprise Data Harvesting
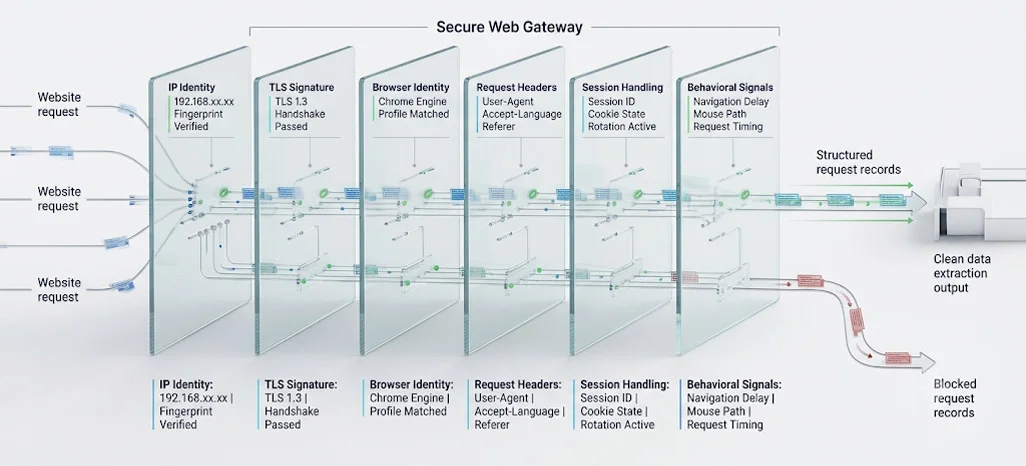
Target environments use sophisticated anti-bot detection tools including IP fingerprinting, TLS signature checks, and behavioral analysis to block automated systems. Overcoming these strict perimeter defenses requires configuring specialized headless nodes that mimic organic human navigation patterns like variable pauses and mouse movement pathing cleanly.
Deploying specialized Web Scraping Services reduces internal engineering maintenance by delegating header management, browser fingerprinting, and session storage to fully managed platforms. This operational shift provides stable access to protected endpoints without risking node blacklisting or unexpected pipeline disruptions.
Enterprise engineering teams implement several core defense mitigation policies across active extraction nodes:
- Dynamic TLS fingerprint spoofing across HTTP headers.
- Humanized event emulation including organic scrolling loops.
- Session preservation using automated cookie persistence strategies.
| Security Defense | Enterprise Mitigation Strategy | Performance Impact |
|---|---|---|
| IP Rate Limiting | Rotational Residential Routing | Sustained Request Velocity |
| Behavioral Profiling | Organic Event Traversal Scripts | Minimal Block Identification |
| Client Fingerprinting | Headless Chrome Profile Patching | High Node Verification |
Integrating headless browser clusters with rotational proxy networks ensures continuous access across high-density extraction schedules. Choosing modern Headless Browser Web Scraping Solutions helps teams bypass network-level rate limits by dynamically routing queries through residential and mobile proxy pools without breaking existing session data.
Robust Quality Validation Systems For High Volume Data Pipelines
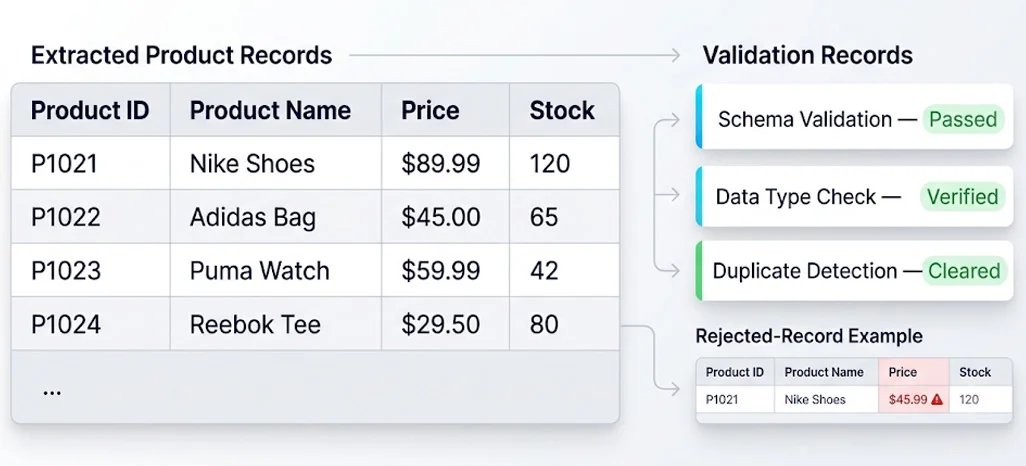
Ensuring high data accuracy across millions of dynamic web pages requires continuous monitoring and multi-stage schema validation frameworks. Modern websites update front-end component structures frequently, which can disrupt fragile parser rules if missing dynamic content checks are not actively built into target extraction scripts.
Building enterprise pipelines using Enterprise Web Scraping strategies ensures that raw payload objects undergo structural validation, data type checking, and anomaly filtering prior to database ingestion. This validation safeguards downstream analytics from malformed dataset records.
Maintaining continuous data integrity across large extraction cycles relies on structured quality checks:
- Pre-ingestion schema assertion across extracted payload fields.
- Automated exception alerts for broken selector paths.
- Real-time statistical anomaly monitoring for record completeness.
| Validation Layer | Implementation Technique | Quality Output Standard |
|---|---|---|
| Element Availability | Wait-for-render conditional checks | Complete Layout Loading |
| Schema Accuracy | Automated JSON Type Validation | Structural Dataset Consistency |
| Data Integrity | Anomaly Detection Alert Triggers | Reliable Stream Ingestion |
Integrating Dynamic Website Scraping techniques empowers data collection systems to adapt instantly to dynamic layout updates and asynchronously loaded components without causing system downtime. Automated wait conditions ensure elements load completely before raw data fields are captured into processing layers.
How Retail Scrape Can Help You?
Navigating enterprise extraction challenges demands customized tools engineered specifically for large-scale data harvesting. Implementing Headless Browser Scraping for Enterprise Scale through dedicated architecture ensures your business collects accurate information from the most challenging digital platforms without technical bottlenecks.
- Advanced browser rendering designed to load dynamic content effortlessly.
- Intelligent proxy rotation configured to bypass sophisticated anti-bot systems.
- Customized web extraction workflows tailored to specific business requirements.
- Automated data validation pipelines ensure unmatched accuracy and structural consistency.
- Real-time monitoring systems keep extraction throughput steady under heavy workloads.
- Continuous maintenance updating selectors automatically whenever target site structures change.
Through integrated Map Monitoring Intelligence, organizations gain complete visibility over pricing shifts, stock availability, and global market trends effortlessly. Utilizing specialized Cloud-Based Browser Scraping Services enables your technical teams to focus on core strategic insights while we manage the complex data extraction infrastructure.
Conclusion
Building stability across enterprise data pipelines requires robust infrastructure capable of handling modern web complexities. Organizations relying on Headless Browser Scraping for Enterprise Scale successfully transform unstructured dynamic content into actionable business intelligence while minimizing block rates and missing records. Enterprise data extraction becomes effortless when technical teams implement scalable architectures built to adapt to evolving web technologies seamlessly.
Maintaining high success rates across millions of web targets demands specialized systems and expert management. Partnering with top-tier Enterprise Scraping Solutions empowers your business to capture reliable market data continuously without maintaining complex internal scraping clusters. Contact Retail Scrape today by integrating robust automated solutions designed for modern enterprise performance.